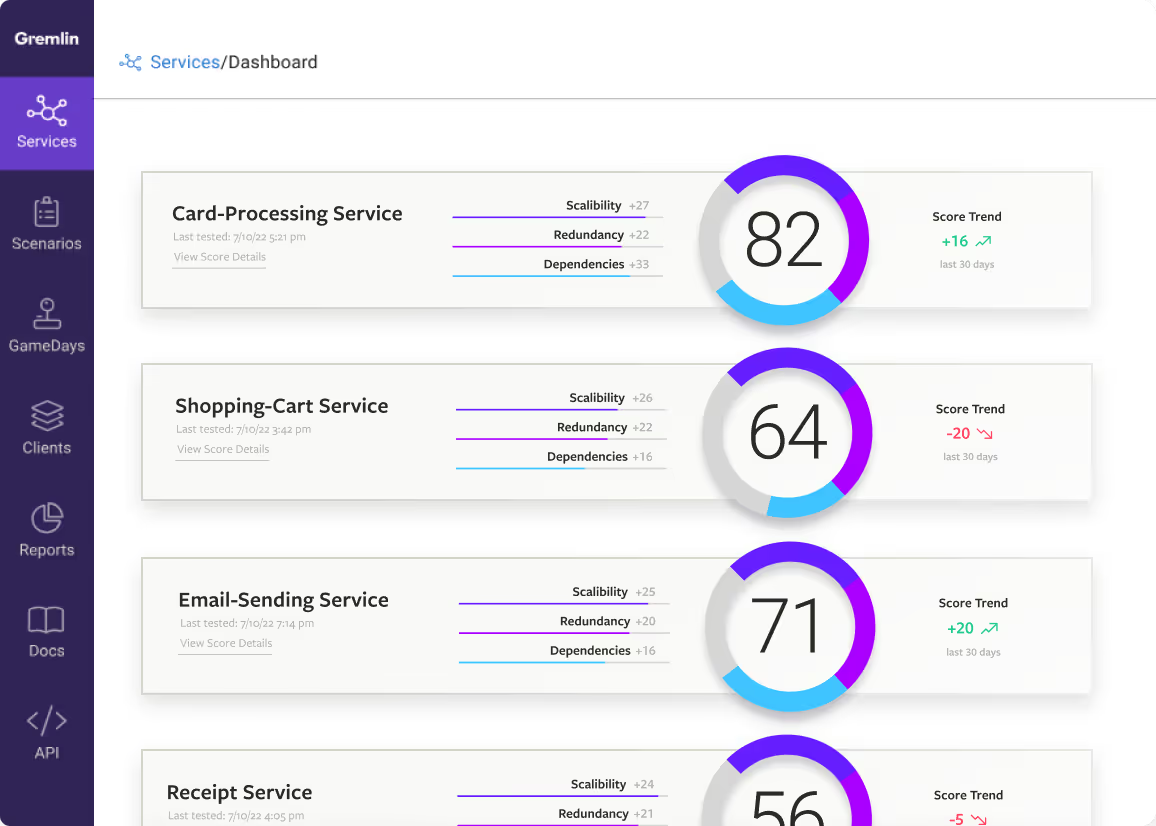
Test EC2 reliability with Gremlin. Run CPU, Memory, Disk, and Shutdown experiments plus built-in reliability tests to validate autoscaling and failover.
Amazon EC2 runs a significant portion of workloads on AWS, which means EC2 failures rarely stay contained to EC2. A single lost instance can cascade into slow response times, failed transactions, and lost revenue long before your monitoring tools show anything unusual.
Track down those failures and prevent them from causing outages with the Gremlin Reliability Platform. Install the Gremlin Agent on your instances, then use Chaos Engineering experiments and standardized Reliability Test Suites to prove your services survive the failures AWS will eventually hand you. With Gremlin, you can:
- Prove your services survive instance loss. AWS retires hosts, degrades hardware, and reclaims Spot capacity on its own schedule. Shutdown experiments let you take an instance offline on your terms and confirm that traffic reroutes, replacements launch, and your customers never notice.
- Validate the Multi-AZ architecture you're paying for. Redundancy on an architecture diagram is not the same as redundancy under load. Blackhole experiments isolate an availability zone so you can watch the remaining zones absorb the traffic, turning an assumption into evidence you can show your leadership team.
- Find resource limits before your customers do. CPU, memory, and disk experiments apply pressure to an instance while you watch how your service responds. You learn where autoscaling triggers, where health checks fire, and where your thresholds were set years ago and never revisited.


CPU scalability - Linux
Test that your Linux-hosted service scales as expected when CPU capacity is limited. Gremlin consumes CPU in three stages—50%, 75%, and 90%—to validate scaling thresholds.
CPU scalability - Containers
Test that your service scales as expected when CPU capacity is limited. Gremlin will consume CPU in 3 stages: 50%, 75%, and 90%.
Region Evacuation - Linux
Test your Linux-hosted service's availability when an entire cloud region becomes unavailable. Verify that traffic automatically fails over to backup regions without impacting the user experience.
Zone redundancy - Linux
Test your Linux-hosted service's availability when a randomly selected availability zone becomes unreachable. Verify that traffic fails over to secondary zones.
* Gremlin is designed to work on any cloud platform that provides Linux or Windows hosts. We haven't individually tested every service we cover, and not all are officially supported. Check our compatibility documentation for tested operating systems and known caveats, or get in touch if you don't see yours.
Intelligent Health Checks - AWS
Automatically monitor your AWS services during testing in one-click with Intelligent Health Checks.
AWS integration
Integrate Gremlin with your AWS account for automatic Health Check creation, service discovery, and more.
Troubleshooting Failure Flags
Diagnose and resolve common issues with Failure Flags, Gremlin's application-based fault injection feature.
Using Failure Flags by proxy
Use Failure Flags, Gremlin's application-level fault injection feature, without changing a single line of code.
Reliability Intelligence: Spread load across replicas to reduce error spikes
Reduce error spikes during replica termination by spreading traffic more evenly across a larger number of pods.
Installing Gremlin on Amazon ECS
Learn how to install Gremlin on EC2-backed Amazon Elastic Container Service (ECS) deployments.
Installing Gremlin on AWS - Configuring your VPC
Amazon Web Services (AWS) has unique networking requirements that must be implemented for Gremlin to run successfully…
Amazon CloudWatch Health Check
Learn how to monitor the health of your systems during testing by using your existing AWS CloudWatch alarms.
Deploying Failure Flags on AWS ECS
This document will walk you through setting up Failure-Flags-Sidecar for your ECS Tasks. Failure-Flags-Sidecar runs…
Deploying Failure Flags on AWS Lambda
This document will walk you through setting up the Failure Flags agent for Lambda Functions. The Failure Flags agent…
Failure Flags
Gremlin Failure Flags lets you run Chaos Engineering experiments and reliability tests on serverless workloads…
Scenarios
A Scenario is a set of Health Checks and Gremlin experiments that you can define, along with a name, description…
Experiments
An experiment is a method of injecting failure into a system in a simple, safe, and secure way. Learn how easy it is to run experiments in Gremlin.
Targets
A target is any infrastructure or application resource that you can run experiments on. This can include Amazon EC…
Services
Gremlin tests your services to ensure they're resilient to traffic surges, network latency, cloud provider blackouts, and more. Learn how in our docs.
Configuring the Gremlin Agent
This documentation page shows you how to configure the Gremlin Agent. You can configure Gremlin using either environment…
Avoid downtime. Use Gremlin to turn failure into resilience.
Gremlin empowers you to proactively root out failure before it causes downtime. See how you can harness chaos to build resilient systems by requesting a demo of Gremlin.