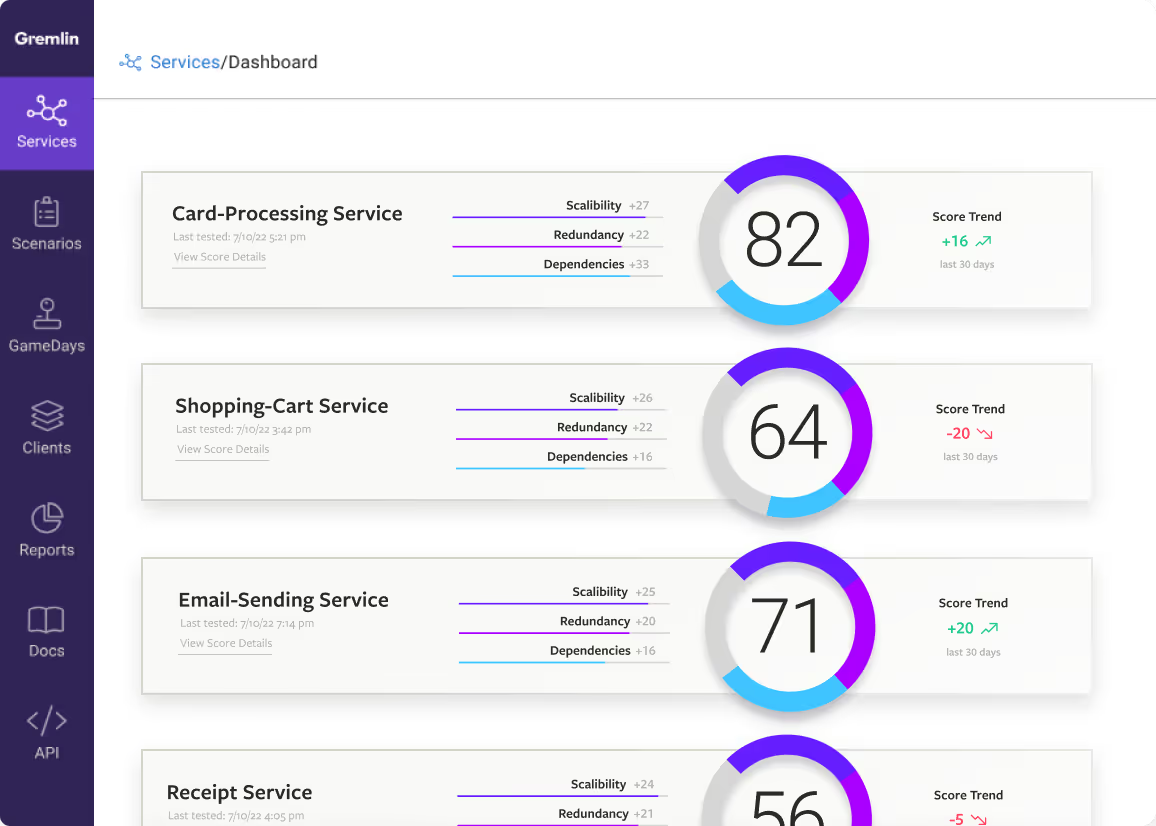
We made reliability something you can measure
We pioneered chaos engineering as something an enterprise could actually do. Today Gremlin is the reliability management platform the world's most reliable companies use to build resilience across everything they ship and run. We find failure modes, fix them, and validate the fix before they become outages—at the pace AI-driven teams are shipping.
Of the largest banks in the US use Gremlin
Availability by using Gremlin on our own platform
We help teams shift from hoping to proving
Most teams judge reliability with metrics like incident counts, MTTR, or uptime that only tell you what already broke. Gremlin works the other direction: it finds the failure modes you haven't validated, tells you what to change, and re-tests to confirm the fix held. This rolls up into a reliability score, so you're measuring it proactively, not guessing between incidents.

Detect
Find risk without a test
Passive detection surfaces configuration drift and deviations from your standards, and maps the service dependencies nobody documented.

Test
Simulate failure
Safely inject faults to see how systems actually respond—not how the architecture diagram says they should.

Fix
Auto-remediate
Foresight AI turns each finding into config patches and IaC diffs drawn from the Failure Atlas, our proprietary record based on millions of real failures.

Prove
Confirm it held
Re-test after the fix, then track a standardized reliability score per service so you can benchmark teams and show progress over time.
Prioritize by actual risk instead of by last quarter's outage
With Gremlin, engineering leaders can answer "are we reliable?" with data instead of "we haven't had a major outage recently." And as more code ships without close human review, that loop becomes the resilience validation your AI can't run on itself.
The only way to improve reliability is to know what will happen to your systems when things go wrong. Everything else is guesswork.

It should be easy to do the right thing.
If improving reliability is hard, teams won't do it—no matter how much they care. We’re devoted to making impactful reliability actions low-lift and repeatable, because that beats thorough and ignored every time.

Safety is a foundation, not a feature.
Customers hand us their production infrastructure, and we take that trust seriously. Safety features like blast radius controls, halt conditions, and more have been part of Gremlin since the beginning.

Expertise belongs in the product.
Every team should get the recommendation a senior SRE would have made—whether or not they have one on staff.
Trusted where downtime isn't an option
Financial services, retail, media, and B2B SaaS companies use Gremlin to build resilience across everything they ship and run.




Less downtime
at a major US insurance company, after standardizing 36 tier-one applications on Gremlin test suites.
Faster full disaster recovery testing
at one of the world's largest banks—4,000 distinct tests run in a tenth of the time.
Critical failure modes found
before a top-5 US bank migrated 100 million customers to a new platform at 99.99% availability.
Built by the people who got paged
Our founders ran outage response at Amazon and Netflix, where they learned that almost every major outage traces back to a failure mode somebody could have found on a Tuesday, instead of at 3 a.m. on the worst possible night.
Kolton Andrus
Co-founder & CEO
Kolton built fault injection at Amazon in 2009 and served as a Call Leader at both Amazon and Netflix, accountable for resolving global outages in real time. He founded Gremlin in 2016 to make that discipline available to every engineering organization.
Sam Rossoff
Chief Technology Officer
Sam leads engineering at Gremlin, where he is responsible for the platform that thousands of services are tested against. Before Gremlin he built large-scale distributed systems at Amazon and Snapchat.
Dave Coughlin
VP, Sales
Dave leads Gremlin's sales organization, partnering with engineering teams across financial services, retail, and SaaS to build reliability programs that scale.
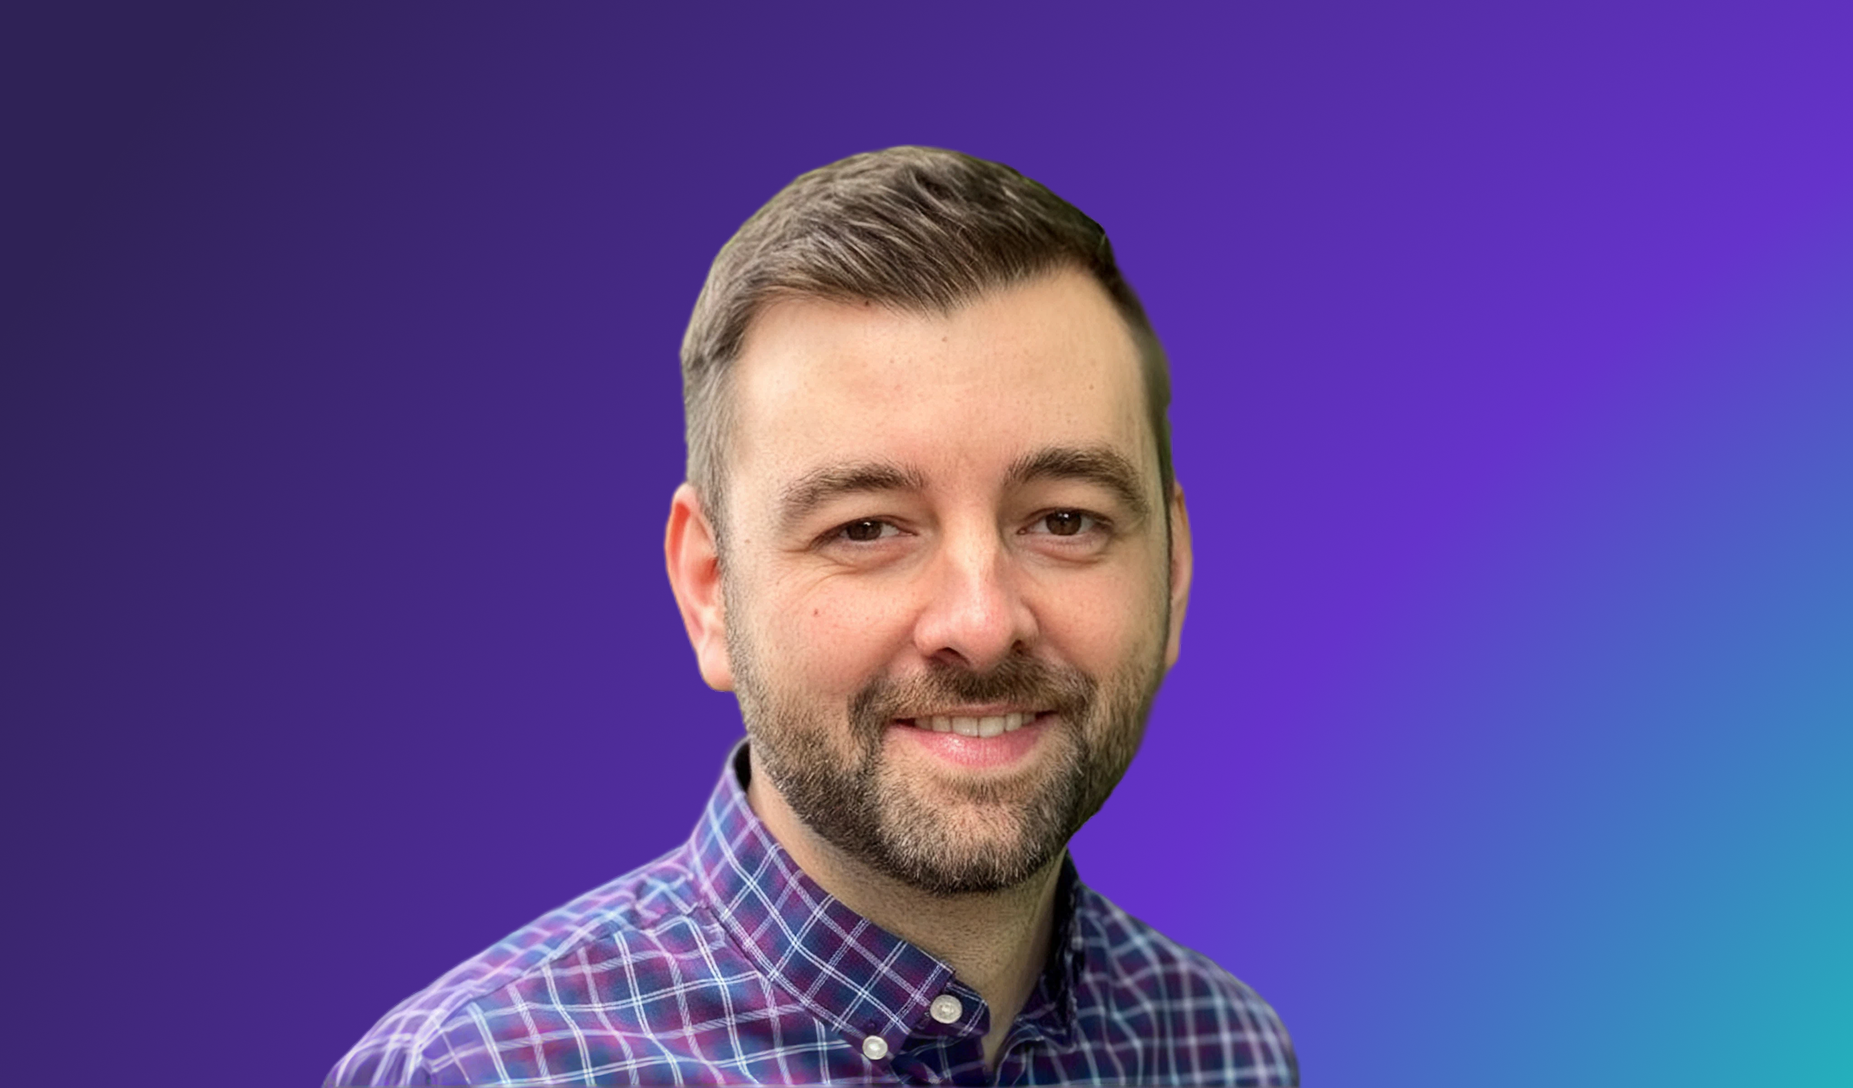
Ryan Detwiller
VP, Marketing
Ryan leads marketing at Gremlin. He has spent his career in product. marketing, and strategy roles across cybersecurity, compliance, networking, and infrastructure, launching products through to enterprise scale.
Backed by
How we got here
2009
Kolton Andrus builds fault injection at Amazon.
2012
Netflix open-sources Chaos Monkey, putting the practice on the map.
2016
Gremlin is founded.
2017
Gremlin launches publicly and raises a $7.5M Series A.
2018
$18M Series B, and the first application-level fault injection.
2019
SOC 2 Type II certification. Chaos engineering comes to Kubernetes.
2022
Gremlin launches the world's first reliability management platform.
2023
Failure Flags brings testing to serverless. The certification program passes 2,000 credentials in its first year.
2025
Private Edition and Reliability Intelligence.
2026
Disaster Recovery Testing, then Foresight AI—supervised agents that find, fix, and verify.
Trust & security
We run inside the world's most regulated production environments. That privilege comes with obligations.
SOC 2 Type II certified
Blast radius controls and automatic halt conditions
Private Edition for fully isolated networks
AWS PrivateLink: no data leaves your cloud
Careers
Remote-first, high productivity, low drama. We hire people who own outcomes and would rather find the failure on a Tuesday.
Fully distributed across North America
Engineers from Amazon, Netflix, Google, Salesforce, New Relic
Avoid downtime. Use Gremlin to turn failure into resilience.
Gremlin empowers you to proactively root out failure before it causes downtime. See how you can harness chaos to build resilient systems by requesting a demo of Gremlin.