5 agentic AI prompts to supercharge your reliability
Teams are shipping more code than ever with AI, but reliability practices haven’t kept pace. Many teams still rely on backwards-looking tools like incidents, logs, and postmortems. AI reliability tools give you a faster path.
In this session, Gremlin's reliability experts walk through five workflows that help you find reliability risks, prioritize what to fix, and show leadership the results. You’ll see the workflows in action, the prompts we use to run them, and leave with a playbook you can use in any AI-assisted reliability workflow.
Register Now
Thank you for registering! You'll recieve a link to join the webinar on November 10th.
AI coding tools let teams ship more code than ever, but reliability practices haven't kept up. Most teams still learn about failures from backwards-looking metrics like incidents, logs, and postmortems. This often means that a customer-facing outage becomes the first real test of a failover plan or retry policy. As deployment frequency increases, so does the cost of the next outage.
In this session, we’ll walk through five workflows that you can use to proactively find and address reliability risks. You'll learn how to use AI-powered reliability tools to spot likely failures early, choose the tests that matter most for your architecture and environment, and turn failed tests into specific remediation steps that you or your coding agents can act on. From there, you'll validate the fix and give leadership a clear view of your team's reliability work and the improvements it produces.
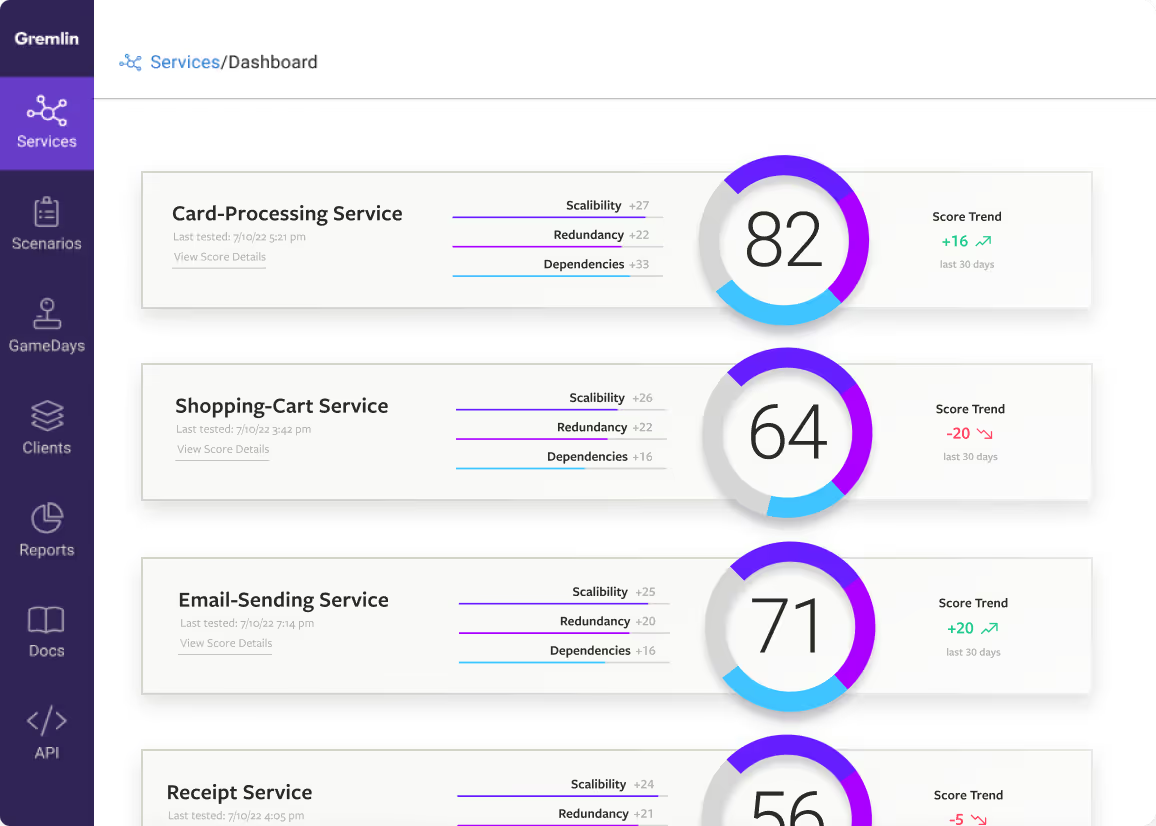
We'll demo each workflow in Gremlin Foresight AI. You'll walk away with a playbook you can use in Foresight AI, or adapt to the AI tools your team uses.
What you'll learn
• How to use AI-powered reliability tools to spot potential system failures before an incident reveals them.
• The keys to dentifying and prioritizing tests to run based on your unique environment and architecture.
• Ways to turn failed tests into specific, guided remediation steps that you or your coding agents can act on, then validate the fix.
• Practical ways to give leadership clear visibility into your team’s reliability efforts and improvements.
Andre Newman
At Gremlin, Andre promotes the benefits of Chaos Engineering and reliability testing to engineering teams around the world, including at some of the largest enterprise organizations. Prior to Gremlin, he created technical content explaining Kubernetes and containerization, the shift to cloud computing, DevOps, observability, and more. His work has been featured in The New Stack, DZone, Software Engineering Daily, TechBeacon, and StatusCode Weekly.

Nicholas Mason
Nick Mason is a Senior Solutions Architect at Gremlin. Before Gremlin, he worked at incident management companies, including Blameless and FireHydrant, where he saw firsthand how often teams were stuck reacting to failures. Now he helps customers build reliability programs that catch risks before they become incidents, using tools like Gremlin's Reliability Management and Foresight AI to speed up how teams find, prioritize, and report on what matters.
Avoid downtime. Use Gremlin to turn failure into resilience.
Gremlin empowers you to proactively root out failure before it causes downtime. See how you can harness chaos to build resilient systems by requesting a demo of Gremlin.