Recreate Incidents and Outages

Top US retailers lose $14,056 per second during downtime. Gremlin pays for itself within days by ensuring your systems withstand real-world failures before they can impact your customers.

Top Fortune 500 organizations worldwide trust Gremlin

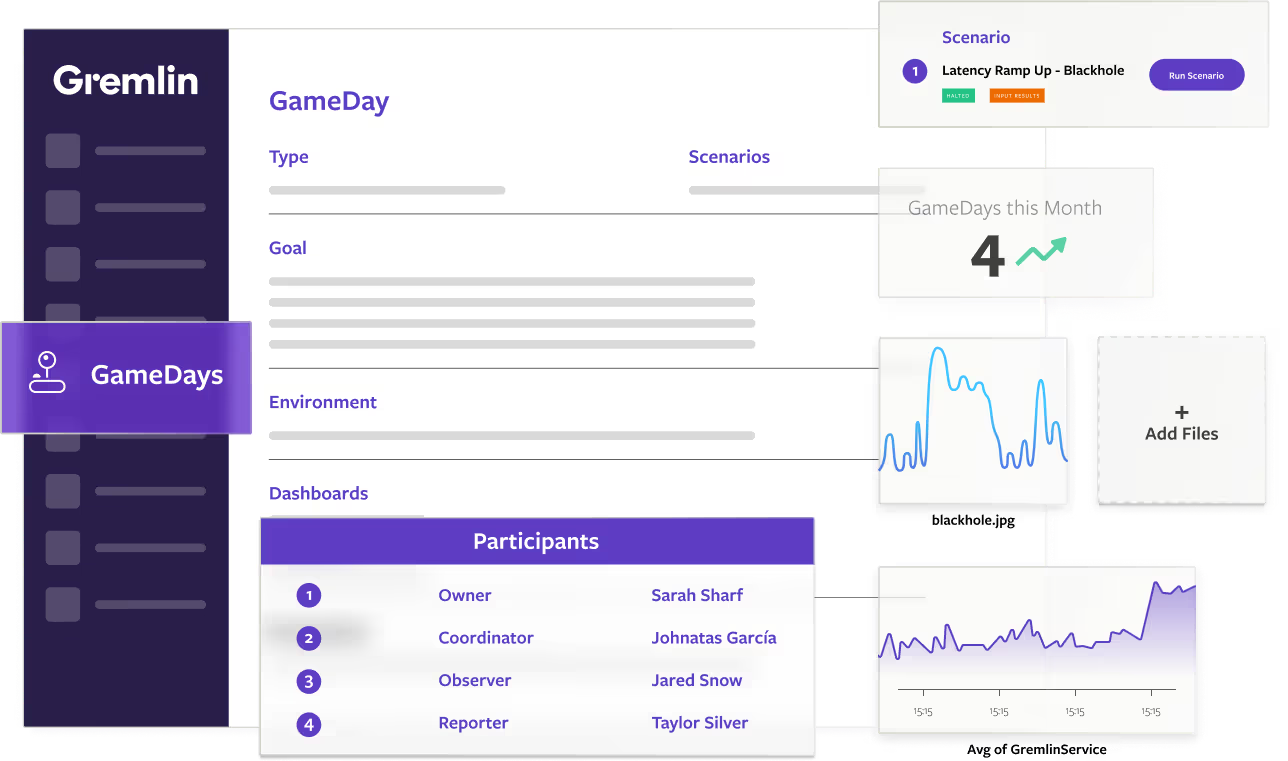
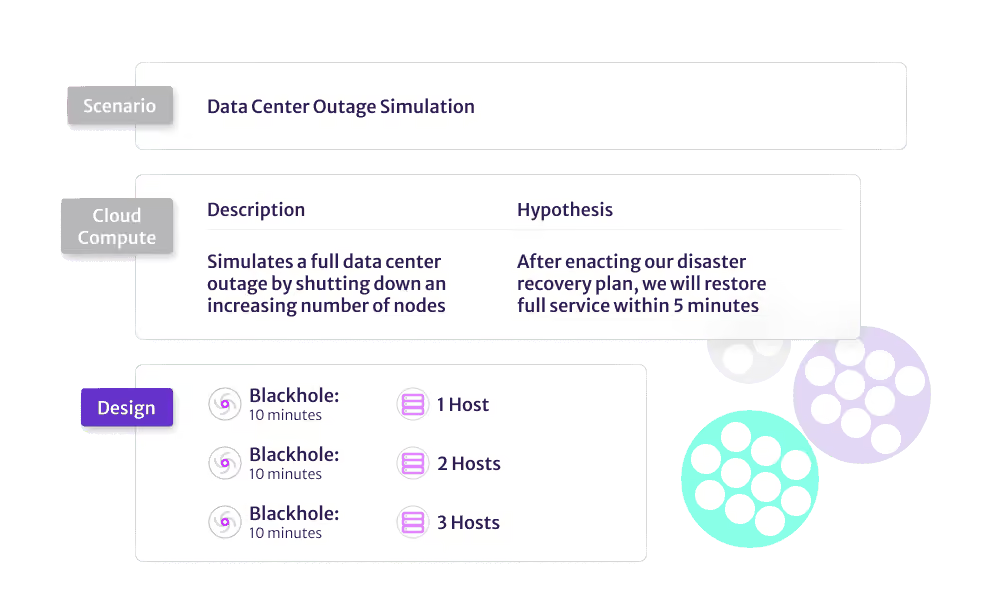
Confidently recreate incidents and outages

  • Simulate real failure scenarios with a comprehensive library of faults
  • Start small, scale confidently: Start with a single host and expand as you build resilience
  • Test safely with automatic rollback based on real-time health metrics
Prepare for any scenario

  • Replicate real-world failures to prevent incidents and stop firefighting
  • Reduce the number of expensive outages and increase customer trust
  • Prevent late nights and burnout so your engineers can do their best work

Empower your SRE and DevOps teams

  • Enable engineers to find hidden reliability risks, ensure reliable launches, and mitigate downtime
  • Validate incident management playbooks and disaster recovery runbooks
  • Meet and track adherence to uptime and availability SLOs

Improve reliability on any platform

  • Run standardized reliability tests and custom faults on cloud, on-prem, Kubernetes, and more
  • Test serverless applications at the code level with Failure Flags
  • Integrate with CI/CD, observability, and performance tools

Shift from observing to improving

Gremlin enables teams to proactively improve reliability at every stage of maturity.

experimenting

Custom Chaos Tests & Experiments

Robust, customizable chaos tests to safely replicate any incident scenario.

Standardizing

Standardized Reliability Tests

Pre-built test suite to cover the most common reliability risks. Get started in minutes.

Scaling

Automated & Scaled Reliability Programs

Standardized scoring tools to identify and prioritize risks, and build reliability programs.

Related resources

blog

Don’t just react to incidents—prevent them

by Gavin Cahill on May 9, 2023

It’s time to go from reactive to proactive. Learn how to align around a reliability map so you can find and fix reliability risks before they become outages.

blog

How to be prepared for cloud provider outages

by Gavin Cahill on Jun 13, 2025

Check out these testing best practices teams should follow to minimize the impact of cloud provider outages so they don’t catch you by surprise.

blog

Reliability lessons from the 2025 Cloudflare outage

by Andre Newman on Nov 20, 2025

In November 2025, a misconfigured Cloudflare service led to a partial outage. Learn what happened, and what you can do to reduce the impact of similar outages.