Test Auto Scaling Group reliability with Gremlin. Trigger CPU and Memory experiments to validate scaling policies and instance replacement.
An Auto Scaling Group is the safety net under everything else you've built on EC2, and it's the component least likely to have been tested. Scaling policies and autohealing only run during the exact conditions you can least afford to have them fail.
Misconfiguration here is quiet. A cooldown period that's too long, a health check that passes on an instance serving errors, or a maximum capacity set below your actual peak will sit dormant for months. Nothing in your dashboards flags them, because from a monitoring perspective the group is doing exactly what it was told.
Bake the Gremlin Agent into your AMI or bootstrap it through user data so every new instance self-registers, then exercise the group deliberately. CPU and memory experiments drive load past your scaling thresholds so you can see where they actually sit relative to the point your application starts degrading. Shutdown experiments confirm that unhealthy instances get replaced, and how quickly traffic stops reaching them.
What you get back is the number you need before your next traffic spike, rather than the assumption you've been running on since the group was created.


CPU scalability - Linux
Test that your Linux-hosted service scales as expected when CPU capacity is limited. Gremlin consumes CPU in three stages—50%, 75%, and 90%—to validate scaling thresholds.
Scalability: Memory
Verify that your Linux-hosted service scales as expected when memory is limited. Gremlin increases memory utilization in three stages—50%, 75%, and 90%—to validate memory management.
Host redundancy - Linux
Test resilience to host failures by shutting down a randomly selected Linux host. Verify that your platform automatically restarts or replaces it.
* Gremlin is designed to work on any cloud platform that provides Linux or Windows hosts. We haven't individually tested every service we cover, and not all are officially supported. Check our compatibility documentation for tested operating systems and known caveats, or get in touch if you don't see yours.
Intelligent Health Checks - AWS
Automatically monitor your AWS services during testing in one-click with Intelligent Health Checks.
AWS integration
Integrate Gremlin with your AWS account for automatic Health Check creation, service discovery, and more.
Troubleshooting Failure Flags
Diagnose and resolve common issues with Failure Flags, Gremlin's application-based fault injection feature.
Using Failure Flags by proxy
Use Failure Flags, Gremlin's application-level fault injection feature, without changing a single line of code.
Reliability Intelligence: Spread load across replicas to reduce error spikes
Reduce error spikes during replica termination by spreading traffic more evenly across a larger number of pods.
Installing Gremlin on Amazon ECS
Learn how to install Gremlin on EC2-backed Amazon Elastic Container Service (ECS) deployments.
Installing Gremlin on AWS - Configuring your VPC
Amazon Web Services (AWS) has unique networking requirements that must be implemented for Gremlin to run successfully…
Amazon CloudWatch Health Check
Learn how to monitor the health of your systems during testing by using your existing AWS CloudWatch alarms.
Deploying Failure Flags on AWS ECS
This document will walk you through setting up Failure-Flags-Sidecar for your ECS Tasks. Failure-Flags-Sidecar runs…
Deploying Failure Flags on AWS Lambda
This document will walk you through setting up the Failure Flags agent for Lambda Functions. The Failure Flags agent…
Failure Flags
Gremlin Failure Flags lets you run Chaos Engineering experiments and reliability tests on serverless workloads…
Scenarios
A Scenario is a set of Health Checks and Gremlin experiments that you can define, along with a name, description…
Experiments
An experiment is a method of injecting failure into a system in a simple, safe, and secure way. Learn how easy it is to run experiments in Gremlin.
Targets
A target is any infrastructure or application resource that you can run experiments on. This can include Amazon EC…
Services
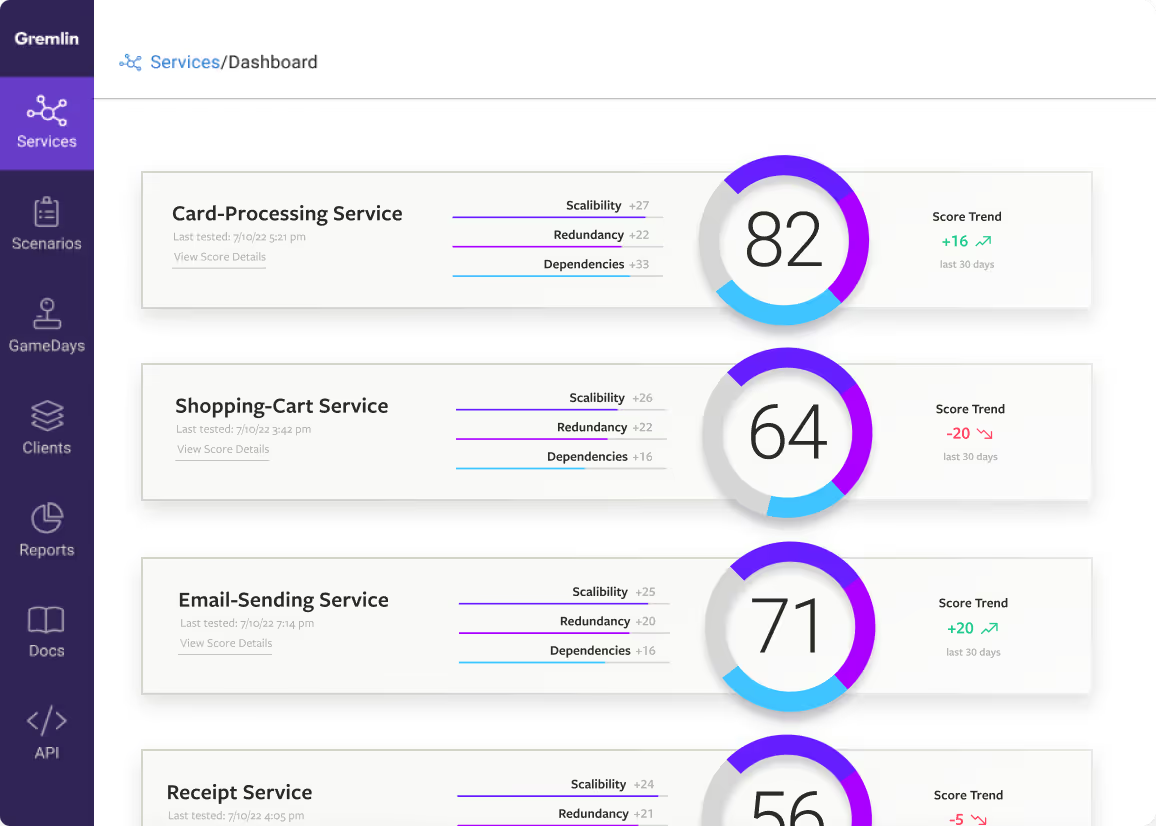
Gremlin tests your services to ensure they're resilient to traffic surges, network latency, cloud provider blackouts, and more. Learn how in our docs.
Configuring the Gremlin Agent
This documentation page shows you how to configure the Gremlin Agent. You can configure Gremlin using either environment…
Avoid downtime. Use Gremlin to turn failure into resilience.
Gremlin empowers you to proactively root out failure before it causes downtime. See how you can harness chaos to build resilient systems by requesting a demo of Gremlin.