Test AWS Amplify reliability with Gremlin Failure Flags. Inject latency and errors into rendering functions to validate fallback pages.
Server-side rendering quietly converts a static site into a live application. The mental model rarely follows. Teams keep treating an AWS Amplify deployment as static hosting, which is famously reliable, while every page view now depends on compute that calls APIs and can stall.
A slow API behind a single component doesn't degrade one widget. It delays the entire rendered response. Visitors see a blank page rather than a partially working one, and search crawlers see a timeout. One misbehaving data source looks exactly like the whole site being down.
Gremlin reaches the render path with Failure Flags. Inject latency into a data fetch and watch what your visitors get. Inject an error and confirm whether your fallback renders cached content, a degraded view, or nothing at all.
Serving something imperfect beats making a visitor wait, but only if someone has verified the fallback actually triggers.


Dependencies: Failure Test
Simulate a failed dependency by dropping all network traffic to the dependency.
Dependencies: Latency Test
Recreate poor network conditions by delaying all network traffic to a dependency by 100ms.
Unreliable Networks - Dependencies
Simulate unreliable network conditions when communicating with dependencies by adding latency to API calls. Test whether your users are affected when dependency response times degrade.
* Failure Flags works wherever you can add the SDK to your application and run the Gremlin sidecar. Not every language and platform combination has been individually tested, and not all are officially supported. Check our compatibility documentation for what's verified, or get in touch if you don't see your runtime.
Intelligent Health Checks - AWS
Automatically monitor your AWS services during testing in one-click with Intelligent Health Checks.
AWS integration
Integrate Gremlin with your AWS account for automatic Health Check creation, service discovery, and more.
Troubleshooting Failure Flags
Diagnose and resolve common issues with Failure Flags, Gremlin's application-based fault injection feature.
Using Failure Flags by proxy
Use Failure Flags, Gremlin's application-level fault injection feature, without changing a single line of code.
Reliability Intelligence: Spread load across replicas to reduce error spikes
Reduce error spikes during replica termination by spreading traffic more evenly across a larger number of pods.
Installing Gremlin on Amazon ECS
Learn how to install Gremlin on EC2-backed Amazon Elastic Container Service (ECS) deployments.
Installing Gremlin on AWS - Configuring your VPC
Amazon Web Services (AWS) has unique networking requirements that must be implemented for Gremlin to run successfully…
Amazon CloudWatch Health Check
Learn how to monitor the health of your systems during testing by using your existing AWS CloudWatch alarms.
Deploying Failure Flags on AWS ECS
This document will walk you through setting up Failure-Flags-Sidecar for your ECS Tasks. Failure-Flags-Sidecar runs…
Deploying Failure Flags on AWS Lambda
This document will walk you through setting up the Failure Flags agent for Lambda Functions. The Failure Flags agent…
Failure Flags
Gremlin Failure Flags lets you run Chaos Engineering experiments and reliability tests on serverless workloads…
Scenarios
A Scenario is a set of Health Checks and Gremlin experiments that you can define, along with a name, description…
Experiments
An experiment is a method of injecting failure into a system in a simple, safe, and secure way. Learn how easy it is to run experiments in Gremlin.
Targets
A target is any infrastructure or application resource that you can run experiments on. This can include Amazon EC…
Services
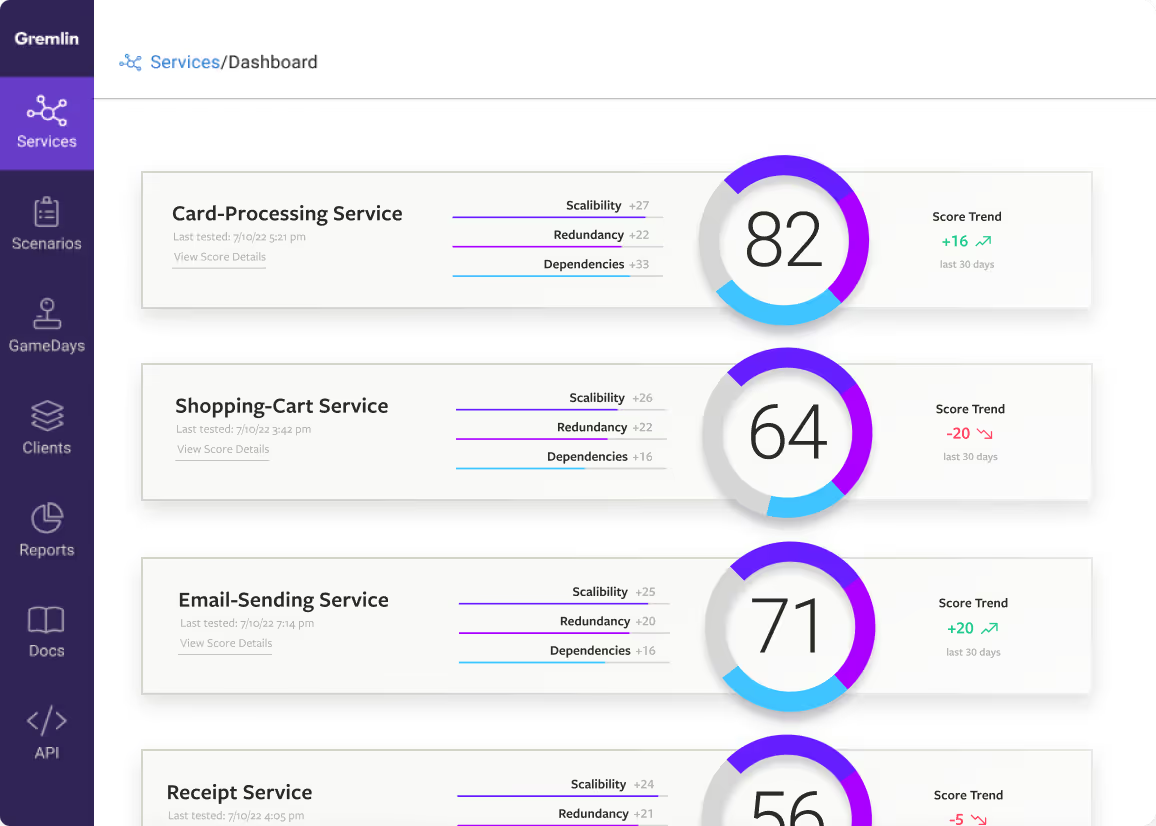
Gremlin tests your services to ensure they're resilient to traffic surges, network latency, cloud provider blackouts, and more. Learn how in our docs.
Configuring the Gremlin Agent
This documentation page shows you how to configure the Gremlin Agent. You can configure Gremlin using either environment…
Avoid downtime. Use Gremlin to turn failure into resilience.
Gremlin empowers you to proactively root out failure before it causes downtime. See how you can harness chaos to build resilient systems by requesting a demo of Gremlin.