Test how your application handles an AWS MSK outage. Run Gremlin network experiments and reliability tests to validate streaming pipeline resilience.
Streaming pipelines on Amazon MSK fail quietly and expensively. When a broker becomes unreachable, nothing crashes. Producers buffer, consumers stall, and lag accumulates at whatever rate your data arrives. The system looks alive the entire time.
The cost compounds rather than accruing evenly:
- A broker or partition becomes unreachable, and the consumers reading from it stop making progress.
- A consumer group rebalance pauses processing further while ownership moves.
- Lag builds at full production rate for the duration, and new traffic keeps arriving on top of the backlog.
- Catching up means processing the backlog alongside live traffic, which takes far longer than the disruption did.
Install the Gremlin Agent on the services producing and consuming, then run a blackhole experiment against broker connectivity to watch the rebalance happen. A latency experiment simulates a lagging broker, which is more common and harder to detect than a clean outage.
Lag is the metric everyone watches after an incident. How fast it drains, and whether your consumers can drain it at all, is worth establishing before the pipeline carries something time-sensitive.


Kafka broker load on Linux
Test the impact of I/O pressure on Kafka broker throughput and partition synchronization on Linux hosts. As disk I/O usage increases on the broker's host, pipeline performance will decrease, but should stay within expected bounds.
Dependencies: Failure Test
Simulate a failed dependency by dropping all network traffic to the dependency.
Dependencies: Latency Test
Recreate poor network conditions by delaying all network traffic to a dependency by 100ms.
* Testing a dependency doesn't require installing anything on it. Gremlin runs the experiment from the service that calls it, so compatibility depends on that host rather than on the dependency itself. Check our compatibility documentation for supported operating systems and platforms, or get in touch if you don't see yours.
Intelligent Health Checks - AWS
Automatically monitor your AWS services during testing in one-click with Intelligent Health Checks.
AWS integration
Integrate Gremlin with your AWS account for automatic Health Check creation, service discovery, and more.
Troubleshooting Failure Flags
Diagnose and resolve common issues with Failure Flags, Gremlin's application-based fault injection feature.
Using Failure Flags by proxy
Use Failure Flags, Gremlin's application-level fault injection feature, without changing a single line of code.
Reliability Intelligence: Spread load across replicas to reduce error spikes
Reduce error spikes during replica termination by spreading traffic more evenly across a larger number of pods.
Installing Gremlin on Amazon ECS
Learn how to install Gremlin on EC2-backed Amazon Elastic Container Service (ECS) deployments.
Installing Gremlin on AWS - Configuring your VPC
Amazon Web Services (AWS) has unique networking requirements that must be implemented for Gremlin to run successfully…
Amazon CloudWatch Health Check
Learn how to monitor the health of your systems during testing by using your existing AWS CloudWatch alarms.
Deploying Failure Flags on AWS ECS
This document will walk you through setting up Failure-Flags-Sidecar for your ECS Tasks. Failure-Flags-Sidecar runs…
Deploying Failure Flags on AWS Lambda
This document will walk you through setting up the Failure Flags agent for Lambda Functions. The Failure Flags agent…
Failure Flags
Gremlin Failure Flags lets you run Chaos Engineering experiments and reliability tests on serverless workloads…
Scenarios
A Scenario is a set of Health Checks and Gremlin experiments that you can define, along with a name, description…
Experiments
An experiment is a method of injecting failure into a system in a simple, safe, and secure way. Learn how easy it is to run experiments in Gremlin.
Targets
A target is any infrastructure or application resource that you can run experiments on. This can include Amazon EC…
Services
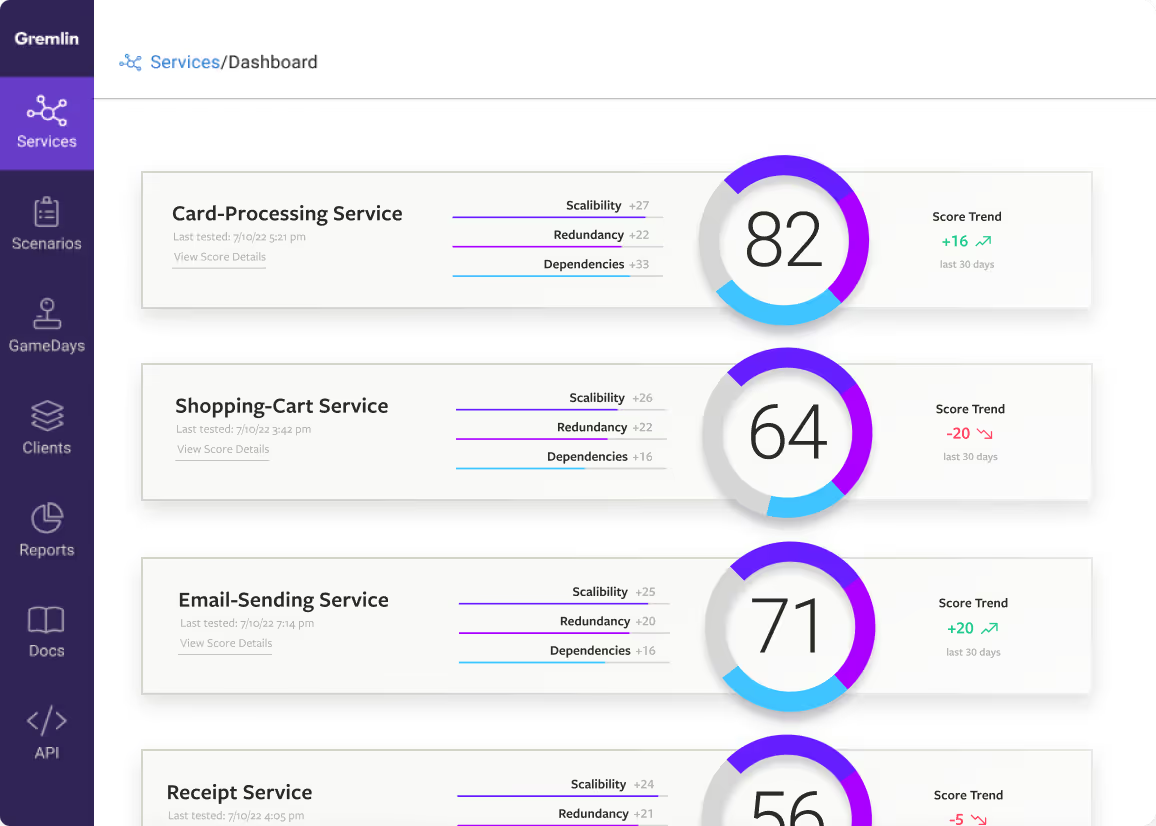
Gremlin tests your services to ensure they're resilient to traffic surges, network latency, cloud provider blackouts, and more. Learn how in our docs.
Configuring the Gremlin Agent
This documentation page shows you how to configure the Gremlin Agent. You can configure Gremlin using either environment…
Avoid downtime. Use Gremlin to turn failure into resilience.
Gremlin empowers you to proactively root out failure before it causes downtime. See how you can harness chaos to build resilient systems by requesting a demo of Gremlin.