How One of the Leading Customer Experience Software Flawlessly Migrated Critical Systems with Gremlin Failure Flags
Gremlin helped a global leader in customer experience software successfully migrate essential business systems without any incidents due to proactive resilience testing.
Simulated failures to verify zero data loss during outages.
Testing ensured zero failures during migration to AWS Lambda.

Executive Summary
A global leader in customer experience software embarked on a migration of essential business systems that had zero margin for error. The systems had to launch on a specific date, couldn’t have any outages, and needed to be able to retain all critical business data. This project was the highest priority for leadership and came with the additional complication of incorporating a new system using AWS Lambda.
By using Gremlin Failure Flags, the IT engineering team succeeded on all counts with flying colors. The migration successfully switched over on day one of the new fiscal year without any incidents due to proactive resilience testing. Additionally, by testing all services using a standardized group of tests, the team proved to business leadership that the systems were reliable and that all critical business data could be successfully retained in case of any future issues or failures.
The Challenge:
How do you ensure a new critical serverless system will be reliable from day one?
Migrations are always complex, and the migration of the company’s key financial and reporting systems was no exception. Made the highest priority by leadership, the migration also came with stiff requirements: it had to happen on the first day of the new fiscal year, and it absolutely had to be reliable from day one.
The system dealt with critical financial data, which made reliability and resilience even more important, including proving to leadership that data wouldn’t be lost in case of errors or outages—even if it happened with third-party systems.
To add a layer of complication, the new system also incorporated key serverless components built on AWS Lambda. Faced with an inflexible deadline, the highest reliability standards, and the complexities of launching a new system, the IT team needed to find a way to detect and prevent outage-causing issues before launch so they could deploy with complete confidence.
The core problem we’re solving is confidence with the business. The business needs to know that we have their data and that we’re taking care of it.”
The Solution:
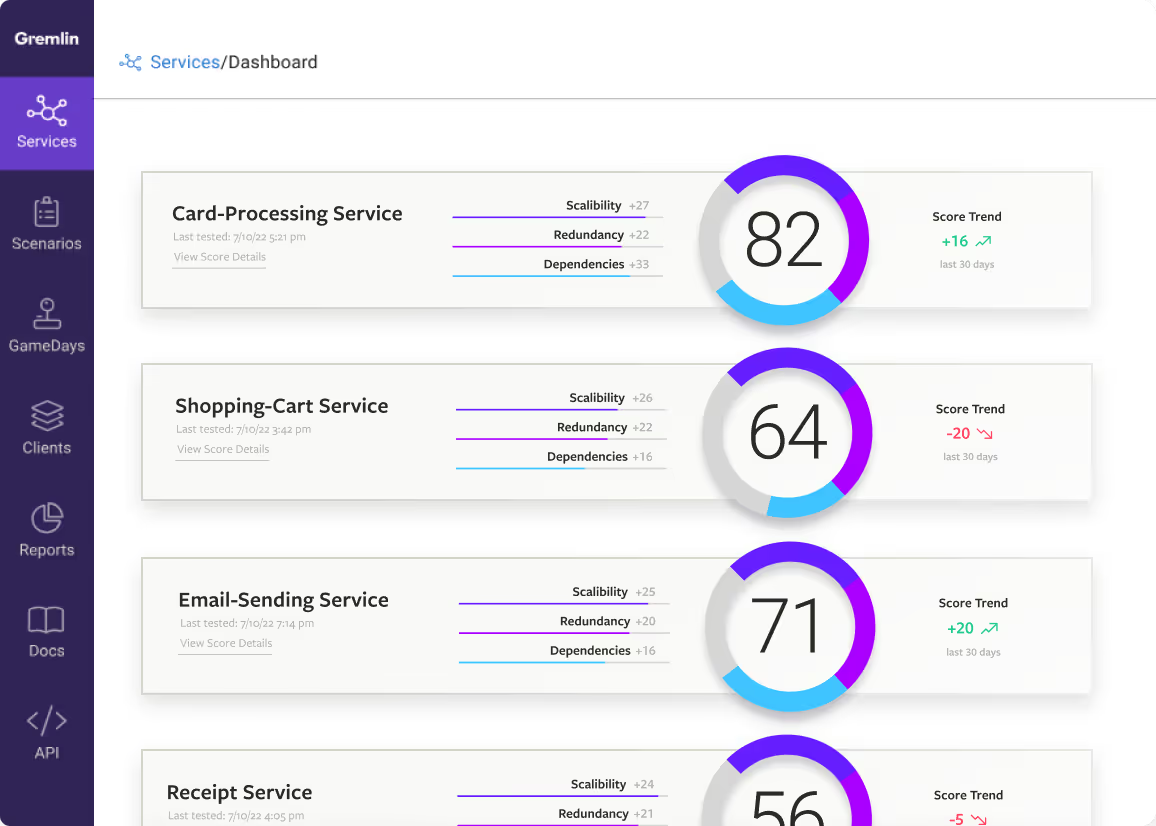
Standardized and regular tests with Gremlin Failure Flags
The IT Director of Engineering Practices turned to Gremlin Failure Flags. Experienced with Chaos Engineering and resilience testing on infrastructures in previous positions, he knew the advantage of proactive reliability tests. Using Failure Flags, Gremlin’s application-level testing for serverless and containers, the Director and his team could run resilience tests on their AWS Lambda functions.
“Systems that go through this process have fewer errors,” said the Director. “And we know that because we’ve shifted left and can see all the errors we’ve found in dev.”
The team developed a standardized list of failures based on experience and causes of actual outages in the past, then refined it with further testing. Before launch, they made sure every service or AWS Lambda call ran through these tests and any issues were addressed.
As a result, when it came time to launch the new system, they were able to flawlessly deploy the AWS Lambda functions in less than five minutes without a single incident or issue.
Of all the parts that went fine, the Gremlin stuff went the most fine. That was without incident. Flip the switch and spend 99 percent of the rest of the time doing everything else. And you can verify that.”
How to build reliable and resilient critical business systems
1. Prove critical business data is safe from failure
When it comes to financial and invoice data, there is zero margin for error. Unfortunately, every system will experience outages at some point, especially when they involve third-party software. To counter this, the IT team built their new system to retain all data when a failure occurs, ensuring that business-critical information isn’t lost.
But it’s one thing to design software to work a certain way and another to confidently know that it will perform as intended. And that’s where Failure Flags comes in. Using Failure Flags, the team could simulate failures and faults directly in their Lambda functions, including latency that leads to API call overload, network outages, and more. They even worked directly with the Salesforce and Workday technical teams to verify that the faults simulated by Gremlin correctly recreated past failures.
As a result, they resolved reliability issues and ensured no data would be lost during outages, timeouts, latency, or other failures. Just as importantly, they were able to show the test results to leadership and prove that the new systems successfully retained business-critical data.
“We need to be able to conclusively show both technical leadership and business leadership that we have records of all of this,” said the Director. “Here are 15 points where it can break in this process, and here's what happens in every one of them. We've proactively done it, and we will continue to proactively redo that weekly as part of our revalidation process.”
2. Confident migration with zero failures
Migrations are notoriously complex projects, often resulting in failures and transition periods with outages or failures. At the company, those outcomes were unacceptable. The new system had to be deployed on February 1st with the start of the fiscal year, and because it included essential financial systems critical for business, it had to be able to run flawlessly from day one.
Resilience testing using Gremlin Failure Flags gave the team the ability to make that happen. They started building a list of tests based on experiences with AWS Lambda and past outages they and other companies had encountered. As their systems began to pass all of these tests, they utilized their Honeycomb integration to perform exploratory testing and uncover unknown failure conditions.
Before long, they had a comprehensive standardized list of tests that could be run on every service. And when migration launch day arrived, they were able to confidently launch their new AWS Lambda services—without any incidents.
It really helped us be more resilient and catch a lot of things beforehand. And since we went live, we've had no problems. Not even a single issue.”
3. Improved reliability posture today and tomorrow
Reliability isn’t a one-time project. A strong reliability posture takes a continued focus built around creating a culture of reliability with standardized, regular testing. And that is exactly what the Director and the IT team are building.
The migration's success showed the company's leadership the effectiveness of resilience testing, which is why regular, standardized testing will be implemented from the beginning of their next major project.
But it takes more than just testing to build more reliable software. A strong reliability posture includes educating engineers and strengthening your observability and incident response practices. Gremlin has helped the company on both counts.
As familiarity with testing grew, engineers began to incorporate greater resiliency into their software, designing improved reliability from the beginning. The team also uses Gremlin to verify and refine their Honeycomb observability and its integration with ServiceNow. By creating failure conditions, they can refine their alerts, verify that tickets and notifications are created correctly, and remediate any issues that would increase the time of detection or remediation.
By using Gremlin, the IT team provided the company with a reliable backbone that leadership can count on to help power their business.
I want to be able to confidently hit merge in GitHub and just know that it's going to show up in Prod in the near future. And I don't have to lose any sleep over it because every problem we've ever had will have been checked as part of go-live.”
Avoid downtime. Use Gremlin to turn failure into resilience.
Gremlin empowers you to proactively root out failure before it causes downtime. See how you can harness chaos to build resilient systems by requesting a demo of Gremlin.